Humanity’s Last Choice: A Common Evaluation Standard for Generative Engine Optimization(人类的最后抉择:生成式引擎优化的通用评估标准)于 2026-10-16 提交到 arXiv,作者 Qianfeng Wen, Yifan Simon Liu, Difan Jiao, Junda Wu, Di Bai, Jintao Liu 等。去 arXiv 读原文,或下载 PDF。
为什么和被引用有关
- 现有基准允许不同的编辑权限,容易把修改自由度带来的收益误认为是优化算法本身的改进。
- 通过优化层级、优化操作和优化信号三个维度,能够系统化描述各种来源修改手段。
- 在测试可见度提升的同时评估原始任务表现,可以避免为了追求引用率而牺牲回答准确度。
- 强制报告评估覆盖范围,能清楚展现哪些策略已被检验、哪些策略空间依然空白。
最重要的一点。 评估生成式引擎优化必须同步规范编辑限制条件与评测指标,确保可见度的提升来自优化技术的有效性,而非不受限制的重写权限。
摘要
Humanity’s Last Choice describes the idea that the last choice people need to make is which AI system they entrust with the decisions that follow. These systems rely on external sources that content providers can edit through generative engine optimization (GEO) to increase source visibility and influence recommendations. Choosing among these systems therefore requires comparable evidence of how well they carry out user requests when exposed to GEO. Benchmarks have made progress in standardizing tasks, models, and metrics, but they often define their own spaces of GEO strategies and use different editing constraints. These differences can conflate gains from better optimization algorithms with those from greater freedom to edit sources, while making evaluation coverage difficult to compare across benchmarks. We therefore call for a common evaluation standard and propose a meta-taxonomy that describes where sources are edited, how they are edited, and what signals those edits target. Drawing on representative literature, we map existing strategies into a searchable space and outline a protocol for controlled comparisons with explicit coverage reporting. This provides a foundation for common leaderboards that can inform which systems people choose to rely on.
译文:“人类的最后抉择”描述了这样一个理念:人类最终只需做出一个决定,即选择信任哪个 AI 系统来代理随后的决策。这些系统依赖外部来源,内容提供者可以通过生成式引擎优化(GEO)编辑这些来源,以提高内容可见度并影响推荐结果。因此,在这类系统之间进行选择,需要可比较的证据来证明它们在面对 GEO 时执行用户请求的表现。现有基准在标准化任务、模型和指标方面取得了进展,但往往自行定义 GEO 方法空间并使用不同的编辑约束。这些差异可能会将更优秀的优化算法所带来的收益,与因拥有更大编辑自由度所带来的收益混为一谈,同时也使得跨基准的评估覆盖范围难以比较。因此,我们呼吁建立一个通用评估标准,并提出一个元分类法,描述来源在哪里被编辑、如何被编辑以及这些编辑针对什么信号。基于代表性文献,我们将现有策略映射到一个可检索的空间中,并概述了带有明确覆盖范围报告的受控比较协议。这为通用的排行榜提供了基础,能够为人们选择依赖哪些系统提供参考。
关键术语
- 生成式引擎优化 (GEO):通过调整外部网页内容,提高其在人工智能生成回答中的被检索率、引用率或推荐排名的技术。
- 优化层级 (Optimization Layer):被修改的文档具体层面,包括字面表层、信息内容、文档结构或面向模型的控制指令。
- 优化操作 (Optimization Action):在文档上执行的具体编辑动作,包括插入、删除、替换、改写、重排、压缩和重组。
- 优化信号 (Optimization Signal):编辑旨在影响模型判断的具体线索,例如权威度、显著度、查询匹配度或证据支撑度。
- 编辑有效性 (Edit Validity):用以检验生成的文档是否严格遵守既定编辑约束和信息保留规则的评估指标。
论文原文
如果各个测试方法使用的编辑权限不一致,仅统一任务和指标并不能实现公平比较。
Existing benchmarks, including C-SEO Bench, E-GEO, and the ranking-manipulation GEO-Bench, have made progress in standardizing tasks, models, and metrics ( Puerto et al., 2025 ; Bagga et al., 2026 ; Nimase et al., 2026 ) . However, shared tasks, models, and metrics do not by themselves define the strategies that methods are allowed to apply.
译文:包括 C-SEO Bench、E-GEO 和排序操纵 GEO-Bench 在内的现有基准,在标准化任务、模型和指标方面取得了进展。然而,仅靠共享的任务、模型和指标本身,并不能界定各方法被允许使用的策略。
编辑自由度不一致会导致评估结果混淆算法能力与修改权限。
A method limited to appending a short sequence and another allowed to rewrite an entire page can be evaluated by the same ranker but operate under different editing permissions. Comparing their scores without accounting for these differences can conflate gains from better optimization algorithms with those from greater freedom to edit sources.
译文:一个仅限于追加短序列的方法与另一个被允许重写整个页面的方法,可以由同一个排序器进行评估,但它们是在不同的编辑权限下运作的。在不考虑这些差异的情况下比较它们的分数,可能会将更好优化算法带来的收益与更大编辑自由度带来的收益混为一谈。
评估必须检查编辑后的内容是否符合保留规则,不能只看可见度是否提高。
Edit validity checks whether the produced source follows the allowed strategy and editing constraints. In the Illustrative GEO Task, an optimizer may change the order of source B, but an edit that also deletes a caveat violates the task constraints even if it achieves a large visibility gain.
译文:编辑有效性检查生成的来源是否遵循允许的策略和编辑约束。在说明性 GEO 任务中,优化器可以更改来源 B 的顺序,但即使删除了警告说明的编辑获得了大幅的可见度提升,它依然违反了任务约束。
论文里的图
该图展示了如何将具体的文档调整拆解为受控的层级、操作与针对信号,并保持核心内容完整。
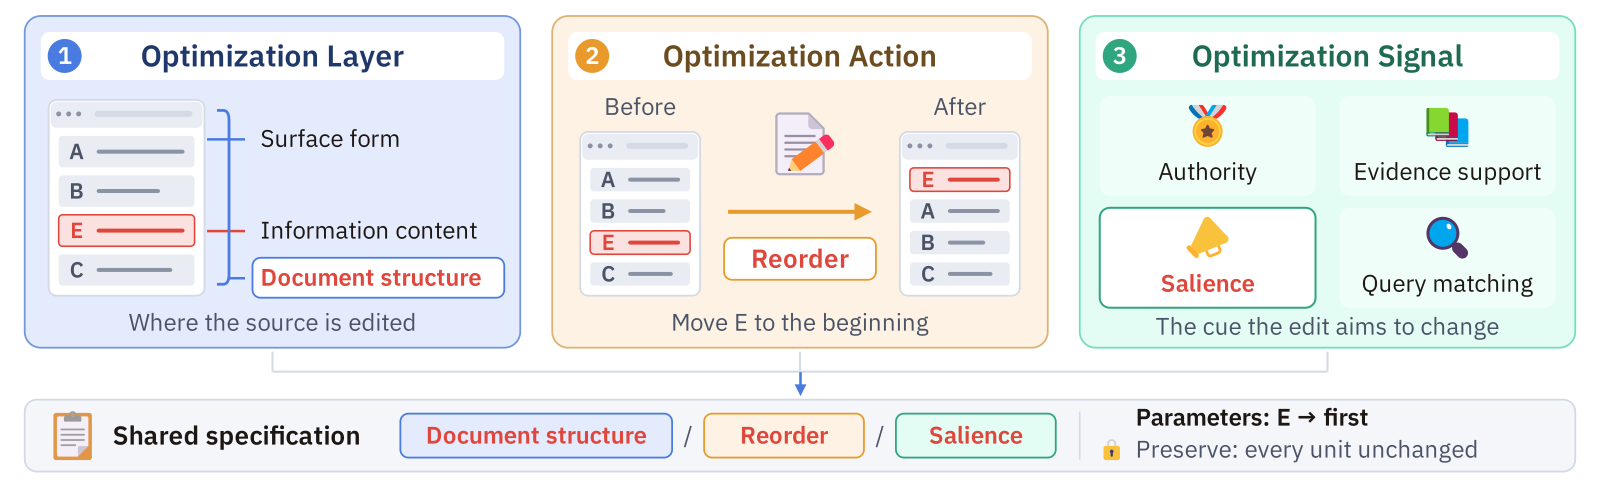
图来自论文 arXiv:2610.23541,版权归作者。原图说明:Figure 1: From a GEO strategy to a shared specification. Moving the existing evidence unit E E to the beginning changes document structure ( Optimization Layer ) through reordering ( Optimization Action ) and targets salience ( Optimization Signal ). The specification identifies the unit and its destination and requires all units, including A A , B B , and C C , to remain intact. The displayed layers and signals illustrate part of the taxonomy.
作者自己说的含义
- 如果不明确限定编辑范围,各家优化工具宣称的效果提升就无法进行横向对照。
- 只测量被引用次数而不检验输出质量的评估方法,容易掩盖模型回答质量下降的问题。
- 利用结构化的分类空间,网站运营者可以更有针对性地梳理影响生成式引擎抓取的页面因素。
可以怎么做
- 依据层级、操作和目标信号三个维度来梳理现有的页面优化动作。 依据:该分类法清晰拆解了内容表层、结构以及针对模型的线索,有助于准确定位起效机制。
- 在测试页面改动对 AI 引用率的影响时,同步监测 AI 生成答案的准确性。 依据:同步记录任务表现可以防止因过度追求曝光度而导致回答失真。
- 在对比不同优化策略前,先界定并锁定统一的文档修改权限和保留规则。 依据:在相同编辑边界下比较策略,才能客观评估优化算法的真实效能。
注意。 该论文提出的是概念框架和规范指南,并未提供大规模实证实验来证明采用该标准能直接提升具体任务的优化效果。
一句话
这篇论文针对生成式引擎优化评测缺乏一致性的问题,提出了覆盖层级、操作与信号的元分类法和评估规范。它主张在统计引用曝光收益的同时,严格检测回答准确率与编辑合规性。这套标准为公平比较各种 AI 系统和优化方法提供了可靠基础。
这篇解读根据论文原文写成,发布前有人看过。引用的段落是原话,数字都是作者自己报告的。方法和完整结果请读论文。