Scoring With the Engine: Retrieval Exposure, Cross-Engine Divergence, and the Limits of Engine-Agnostic GEO Scores(结合引擎进行评估:检索暴露、跨引擎分歧以及通用 GEO 评分的局限性)于 2026-09-19 提交到 arXiv,作者 Benjamin Tannenbaum。去 arXiv 读原文,或下载 PDF。
为什么和被引用有关
- 在四个主流生成式引擎中,相同提示词下的平均两两精确 URL 重合度仅为 0.0079,且 84.9% 的引擎对之间没有共有引用。
- 在测试收集到的全部 URL 中,多达 96.4% 的链接仅被单一引擎引用。
- 在四个引擎同时覆盖的 10 个提示词中,前五位精确 URL 在全部 60 组两两比对中的重合度均为零。
- 实际观察到的跨引擎 URL 重合度仅为相同规模超几何随机基线预测值的 5.7%。
- 单个引擎引用的 URL 数量仅占四个引擎合并 URL 总池的 11.4% 至 42.6%。
- 针对同一引擎在连续两日间的跟踪显示,引用的 URL 集合平均换手率达到 67.0%。
最重要的一点。 脱离具体引擎计算的内容分数只能衡量页面质量或查询相关度,若不建立针对各引擎检索暴露机制的模型,就无法预测线上的实际引用可见性。
摘要
Recent work asks whether generative-engine visibility can be approximated with deterministic, engine-free page scores. We separate two stages such scores can conflate: exposure to a live engine and citation selection conditional on exposure. In an observational audit of ChatGPT, Microsoft Copilot, Google, and Perplexity, 15 fixed commercial prompts produced 589 citation observations on 6 June 2026, corresponding to 528 unique URLs and 356 domains. Same-prompt cross-engine URL overlap was extremely small: mean pairwise Jaccard similarity was 0.0079, the median was zero, and 84.9% of engine pairs shared no cited URL. On the ten prompts observed on all four engines, mean exact-URL Jaccard was 0.0072. A matched-size hypergeometric baseline preserving each prompt’s four-engine URL universe and each engine’s list length predicts 0.1272, so observed overlap was only 5.7% of that baseline; zero URL overlap occurred in 86.7% of comparisons versus 12.3% expected. Top-five exact-URL overlap was zero in all 60 pairwise comparisons. A single engine captured only 11.4%-42.6% of the four-engine URL union, and 96.4% of observed URLs appeared in only one engine. A separate 5-to-6 June same-engine comparison found 67.0% mean URL-set turnover. These results do not invalidate engine-free page scoring; they identify its estimand. A score computed without a live engine can estimate page quality or query-page fit, while end-to-end visibility additionally depends on engine-specific exposure and selection. We therefore argue for reporting page fit, observed exposure, conditional selection, and final visibility as distinct quantities.
译文:近期研究探讨了生成式引擎的可见性是否可以通过确定性的、脱离具体引擎的网页评分来估算。我们将此类评分容易混淆的两个阶段进行了拆分:即面对线上引擎的检索暴露,以及在暴露前提下的引用选择。在针对 ChatGPT、Microsoft Copilot、Google 和 Perplexity 的实证审计中,15 个固定商业提示词于 2026 年 6 月 6 日共产生了 589 次引用记录,对应 528 个独立 URL 和 356 个域名。在相同提示词下,跨引擎的 URL 重合度极低:平均两两 Jaccard 相似度仅为 0.0079,中位数为零,84.9% 的引擎组合之间没有任何共同引用的 URL。在四个引擎均有测试记录的 10 个提示词中,平均精确 URL Jaccard 相似度为 0.0072。保持各提示词四引擎 URL 全集和各引擎列表长度不变的超几何基线预测重合度为 0.1272,实际重合度仅达到该基准的 5.7%;零重合出现的比例在实际比对中高达 86.7%,而基线预期仅为 12.3%。在前五位精确 URL 比对中,全部 60 组两两对比的重合度均为零。单一引擎仅能覆盖四引擎合并 URL 池的 11.4% 至 42.6%,且 96.4% 的被引用 URL 仅出现在单一引擎中。另外对 6 月 5 日至 6 日同引擎的比对发现,URL 集合的平均换手率达到 67.0%。这些结果并未否定无引擎网页评分的价值,而是界定了其测算目标。脱离线上引擎计算的分数可以评估页面质量或查询匹配度,而全流程可见性还需要取决于各引擎特有的暴露与筛选机制。因此,我们建议将页面匹配度、观察到的暴露、条件筛选和最终可见性作为独立指标分别呈现。
关键术语
- 生成式引擎优化 (GEO):通过调整和优化网页内容结构,以提升其在 AI 生成答案中的收录率、展示排名和引用概率的技术方法。
- Jaccard 相似度:通过两个集合的交集大小除以并集大小来衡量两者重合比例的数学指标。
- 超几何基线:假设从固定的候选池中进行不放回随机抽取时,用以预测两个子集之间重合数量的理论概率基准。
- 倒数排名加权重合度:一种对排在列表靠前位置的共有元素赋予更高权重的相似度计算方式。
- 估算目标 (Estimand):统计测量或评估体系在设计上真正想要明确测算的核心物理量或属性。
论文原文
商业提示词在不同 AI 搜索引擎中引发的参考引用链接几乎完全不同。
On 6 June 2026, a fixed benchmark of 15 commercial prompts produced 589 citation observations across ChatGPT, Microsoft Copilot, Google, and Perplexity, corresponding to 528 unique exact URLs and 356 domains. Same-prompt cross-engine URL overlap was extremely small: mean pairwise Jaccard similarity was 0.0079 (prompt-clustered bootstrap 95% CI 0.0037–0.0132), the median was zero, and 84.9% of engine pairs shared no cited URL.
译文:在 2026 年 6 月 6 日,针对 ChatGPT、Microsoft Copilot、Google 和 Perplexity 运行的 15 个固定商业提示词基准共产生了 589 次引用记录,对应 528 个独立精确 URL 和 356 个域名。相同提示词下跨引擎的 URL 重合度极低:平均两两 Jaccard 相似度为 0.0079(提示词聚类自助法 95% 置信区间为 0.0037 至 0.0132),中位数为零,84.9% 的引擎组合没有共享任何被引 URL。
离线计算的评分与决定实际引用可见性的上游阶段属于不同范畴。
A score computed without a live engine can estimate page quality or query-page fit, but end-to-end visibility additionally depends on engine-specific exposure and selection. We formalize this distinction, connect it to recent work on GEO, query rewriting, RAG set selection, source attribution, citation absorption, and generative-search auditing, and propose reporting page fit, observed exposure, conditional selection, and final visibility as separate quantities.
译文:脱离线上引擎计算出的分数可以评估页面质量或查询匹配度,但端到端可见性还额外取决于特定引擎的暴露与筛选过程。我们对这一区别进行了形式化定义,并结合近期关于 GEO、查询重写、RAG 集合选择、来源归属、引用吸收和生成式搜索审计的研究,建议将页面匹配度、实测暴露、条件筛选和最终可见性作为独立指标分别呈现。
即便不同模型具有相同的偏好逻辑,检索候选池的差异也会导致最终引用的完全分化。
Two production engines can therefore share the same conditional preference over exposed pages and yet produce arbitrarily different end-to-end citation distributions if their exposure functions differ. Conversely, similar final citation rates can conceal different exposure and conditional-selection mechanisms.
译文:因此,如果两个线上引擎的暴露函数存在差异,即使它们对已暴露页面具有完全相同的条件偏好,也可能产生截然不同的端到端引用分布。反过来,相似的最终引用率也可能掩盖了完全不同的暴露与条件筛选机制。
论文里的图
该图展示了相同提示词下各引擎两两比对时无论在精确 URL 还是域名层面都接近于零的重合比例。
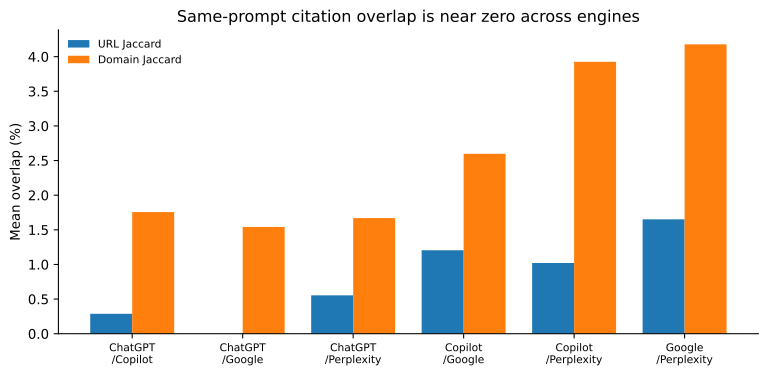
图来自论文 arXiv:2609.22655,版权归作者。原图说明:Figure 1: Mean pairwise Jaccard overlap of cited exact URLs and domains for the same prompt on 6 June 2026.
该图将实测的精确 URL 重合度与在候选池中随机抽取所预期的理论基线进行了对比。
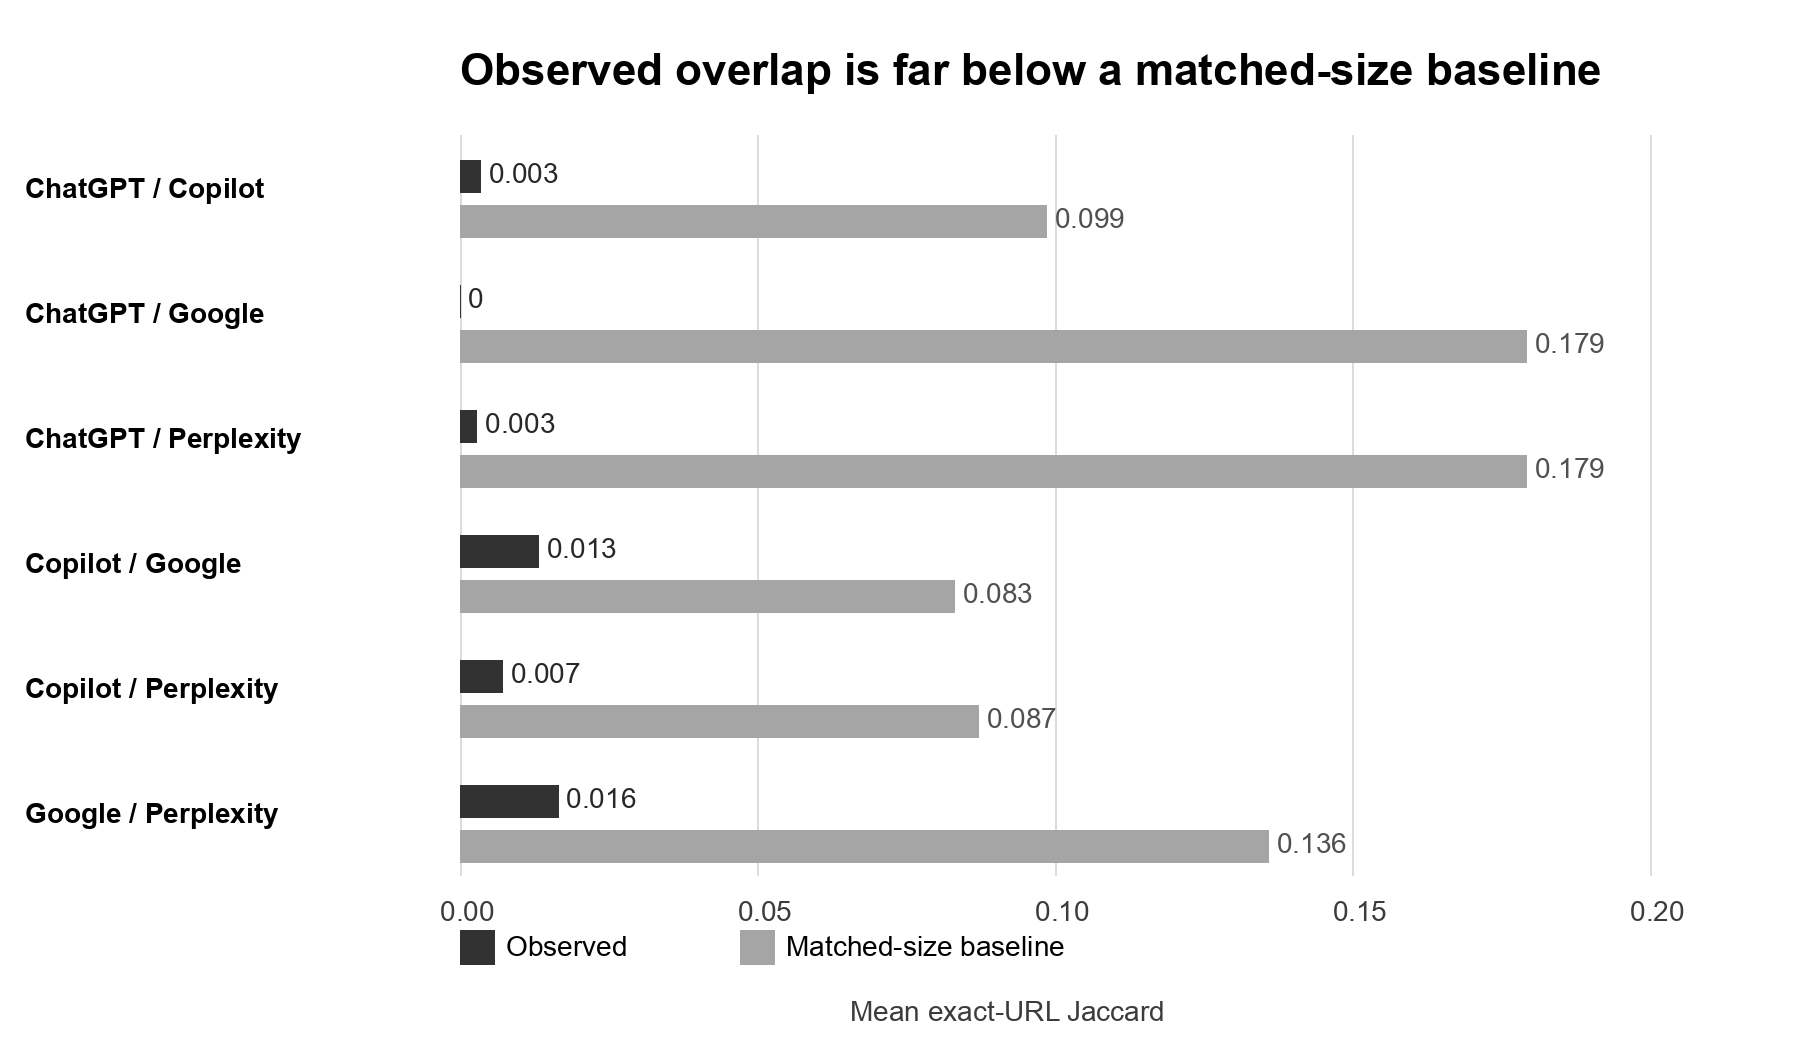
图来自论文 arXiv:2609.22655,版权归作者。原图说明:Figure 3: Observed exact-URL Jaccard versus the prompt-specific matched-size random-overlap baseline on ten prompts observed on all four engines. The baseline preserves each prompt’s four-engine URL universe and each engine’s number of cited URLs.
作者自己说的含义
- 监测单家 AI 引擎的引用表现无法准确代表其他生成式搜索平台的收录情况。
- 在某一家平台上获得靠前的引用排名,并不意味着在竞品平台上也能拥有基础可见度。
- 评估体系应当将页面内容质量、检索召回暴露以及生成阶段的引用挑选作为独立变量分别考察。
可以怎么做
- 针对每个目标 AI 搜索引擎分别搭建监测流程,避免依赖单一平台的测试结果。 依据:
- 重点排查各引擎在收到用户提问后的二次查询重写机制,确保网页能进入初筛候选池。 依据:
- 在调整网页优化策略前持续跟踪同引擎的多日波动,避免将正常的检索换手误判为质量问题。 依据:
注意。 该项研究仅基于 15 个与 AI 监测工具相关的商业提示词展开,且指标依赖严格的 URL 精准匹配而未包含语义层面的内容去重归并。
一句话
主流 AI 搜索引擎在面对相同查询时引用的信源几乎毫无重合。站长和创作者不能指望靠通用的离线内容打分来保证收录,而需要针对不同引擎的上游检索特征分别进行跟踪。想要在 AI 搜索生态中建立稳定的可见度,必须同时兼顾前期的检索暴露和后期的模型挑选两个阶段。
这篇解读根据论文原文写成,发布前有人看过。引用的段落是原话,数字都是作者自己报告的。方法和完整结果请读论文。