‘If I Had to Buy Just ONE: Galaxy S26 Ultra’: Auditing AI-Generated Product Recommendations(‘如果只能买一款:Galaxy S26 Ultra’:AI 生成商品推荐审计)于 2026-09-16 提交到 arXiv,作者 Lucas G. Uberti-Bona Marin, Thales Bertaglia, Giovanni Astante, Bram Rijsbosch, Gijs van Dijck, Anikó Hannák 等。去 arXiv 读原文,或下载 PDF。
为什么和被引用有关
- 不同平台呈现推荐的语气差异很大,在提供产品推荐的回复中,ChatGPT 有 79% 使用了第一人称偏好表达,而 Gemini 只有 7%,Google AI Overviews 只有 2%。
- 不同 AI 搜索引擎引用的信息来源重合度极低,ChatGPT 和 Gemini 的网页界面平均只有 5.4% 的展示域名相同,76.7% 的比对中没有一个共同域名。
- 面向开发者的 API 无法反映普通用户的实际体验,ChatGPT 网页端与 API 之间的平均域名重合率只有 12.0%,Gemini 只有 14.8%。
- 同一模型在多次重复相同提问时会给出不同的推荐商品并展示新的引用来源,单次回答无法代表整体输出。
最重要的一点。 若想评估或优化品牌在 AI 中的推荐展示,必须直接针对面向消费者的网页端进行多次重复测试,不能依赖开发者 API 数据。
摘要
Consumers increasingly use AI chatbots for advice on what to buy. With companies like OpenAI and Google monetising their AI through advertising, this raises difficult questions about the bias and impartiality of such advice. In response, we conduct an AI audit of popular chatbots using real commercial-advice queries. First, we curate a dataset of 2,528 real commercial-advice queries (ConsumerQ). Then, we evaluate 1,536 responses to product queries from popular AI chatbots: ChatGPT (chatbot and API), Google Gemini (chatbot and API), and Google Search (AI Overviews). We find that ChatGPT expresses a first-person product preference in 79% of product-recommending responses, compared with 7% for Gemini and 2% for AI Overviews, while the products recommended often change across repeated requests. Displayed sources vary strongly: for the same query, the ChatGPT and Gemini interfaces share only 5.4% of domains on average, with no domain in common in 76.7% of comparisons. APIs provide a different view from their corresponding interfaces, with mean domain overlaps of 12.0% for ChatGPT and 14.8% for Gemini, and also differ in the types and layers of source information they expose. Our findings show that neither isolated responses nor API observations can be assumed to represent the commercial advice consumers encounter. Independent audits of AI-mediated commercial advice should therefore account for repeated responses, consumer-facing conditions, and the source layer being observed.
译文:消费者越来越依赖 AI 聊天机器人获取购物建议。随着 OpenAI 和谷歌等公司通过广告将其 AI 商业化,这种建议的偏见与客观性引发了严峻问题。对此,我们利用真实的商业咨询查询对主流聊天机器人进行了 AI 审计。首先,我们构建了包含 2528 个真实商业咨询查询的数据集(ConsumerQ)。随后,我们评估了主流 AI 聊天机器人针对商品查询生成的 1536 条回答,涵盖 ChatGPT(网页端与 API)、Google Gemini(网页端与 API)以及 Google 搜索(AI Overviews)。研究发现,在提供商品推荐的回答中,ChatGPT 有 79% 使用了第一人称表达商品偏好,而 Gemini 仅为 7%,AI Overviews 仅为 2%,并且推荐的商品在多次重复请求中经常发生变化。展示的信息来源差异极大:针对相同查询,ChatGPT 和 Gemini 网页端平均仅共享 5.4% 的域名,在 76.7% 的对比中甚至没有任何共同域名。此外,API 呈现的结果与其对应的前端界面大相径庭,ChatGPT 的平均域名重合度为 12.0%,Gemini 为 14.8%,二者在公开的信息来源类型与层级上也存在差异。我们的研究结果表明,单次生成的回答或来自 API 的观察都不能代表消费者实际接触到的商业建议。因此,针对 AI 商业建议的独立审计必须充分考虑重复请求、面向消费者的实际使用环境以及所观察的信息源层级。
关键术语
- 商业咨询查询 (Commercial-Advice Query):用户为了获取选购建议、产品对比或购买确认而向 AI 助手提出的明确咨询问题。
- 第一人称偏好 (First-Person Preference):AI 系统在回复中使用‘我推荐’或‘我的首选’等主观人称口吻来推介特定商品的表达方式。
- 杰卡德重合度 (Jaccard Overlap):通过将两组集合的交集大小除以并集大小来衡量来源或产品相似比例的统计指标。
- AI 概览 (AI Overviews):谷歌搜索结果顶部自动生成的 AI 摘要模块,用于整合网页内容并快速回答用户检索。
- 支撑信源 (Grounding Sources):AI 系统在生成回答时用来验证事实、提供依据并作为引用来源展示的底层网页或文档。
论文原文
各家 AI 聊天机器人在直接推荐商品的表达方式上存在明显不同。
ChatGPT expressed a first-person preference in 79% of product-recommending responses, compared with 7% for Gemini and 2% for AI Overviews, and labelled products as “best” considerably more often. The systems therefore differ not only in what they recommend, but in how they present the recommendation: from explicit personal endorsement to a more qualified presentation of alternatives.
译文:在给出商品推荐的回复中,ChatGPT 有 79% 表达了第一人称偏好,相比之下 Gemini 仅有 7%,AI Overviews 仅有 2%,并且 ChatGPT 将商品标记为‘最佳’的频率要高得多。因此,这些系统不仅在推荐内容上存在差异,在呈现推荐的方式上也大不相同:从明确的个人背书到更审慎的备选方案陈述均有出现。
不同 AI 系统在回答同一商品咨询时几乎不会引用相同的媒体域名。
For the same query, ChatGPT and Gemini share, on average, 5.4% of displayed domains, and 76.7% of comparisons share no domain at all.
译文:针对同一个查询,ChatGPT 和 Gemini 平均仅共享 5.4% 的展示域名,并且在 76.7% 的对比中二者没有任何共同域名。
通过开发者 API 获取的引用信源无法如实反映普通用户在网页界面上看到的内容。
For identical queries submitted moments apart, ChatGPT’s interface and API share only 12.0% of displayed domains on average; for Gemini, the overlap is 14.8%.
译文:对于前后相隔数秒提交的完全相同查询,ChatGPT 的界面与 API 平均仅共享 12.0% 的展示域名;对于 Gemini,这一重合度为 14.8%。
论文里的图
图表展示了三种用户界面在推荐语气上的差异,ChatGPT 使用第一人称偏好并把单一产品评为最佳的比例明显高于 Gemini 和 AI Overviews。
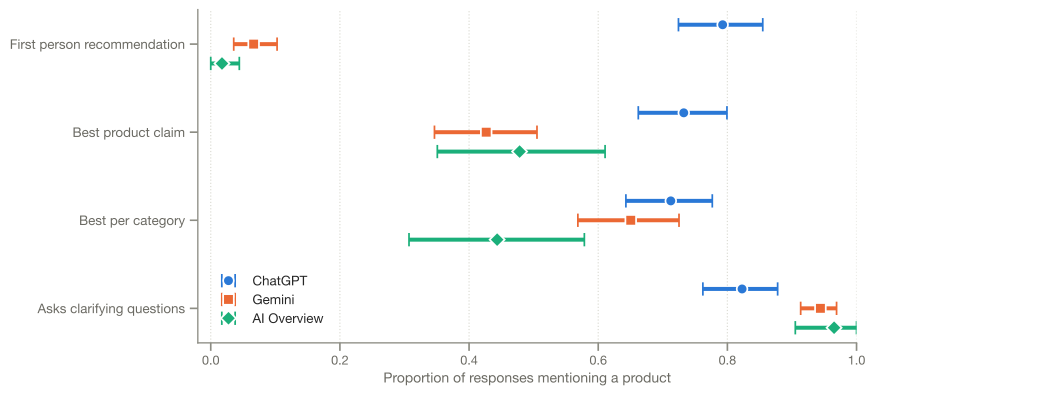
图来自论文 arXiv:2609.18729,版权归作者。原图说明:Figure 2: ChatGPT more often highlights options as the best and/or its pick/recommendation. Product recommendation framing across the three consumer interfaces. Bars show the share of the answers naming a product that contains each measured property; whiskers are 95% bootstrap CIs over the queries.
数据显示当界面与 API 引用出现分歧时,绝大多数情况下是引用了完全不同的域名,而不是同域名下的不同页面。
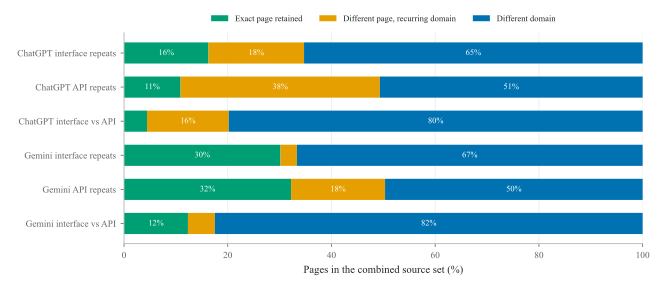
图来自论文 arXiv:2609.18729,版权归作者。原图说明:Figure 5: When the interface and API disagree on sources, they usually disagree on the domain itself. Pages from domains appearing on only one side account for 79.8% of the ChatGPT interface–API union and 82.5% of the Gemini union. The remaining pages are either exact matches or different pages from domains appearing on both sides.
作者自己说的含义
- 营销人员不能把后端 API 调用的检测结果当作终端用户在网页端看到的 AI 推荐情况。
- 由于重复提问会不断唤起新的信源,媒体机构需要持续扩大在相关评测领域的全网覆盖度。
- ChatGPT 倾向于直接给出带个人色彩的结论,而谷歌系统倾向于罗列备选方案,品牌在这两类环境中的展示逻辑完全不同。
可以怎么做
- 直接在面向消费者的网页端界面采集 AI 商品推荐结果。 依据:论文发现网页界面与开发者 API 之间的平均域名重合度在 ChatGPT 中仅为 12.0%,在 Gemini 中仅为 14.8%。
- 在监测品牌推荐情况时对同一问题进行多次重复提问以捕捉波动。 依据:研究表明重复提交相同问题会改变推荐的商品列表并持续出现新的引用域名。
- 针对不同平台分别布局第三方评测媒体而不是指望同一套信源通吃。 依据:实验显示 ChatGPT 和 Gemini 之间平均仅有 5.4% 的共有展示域名,超七成情况下完全没有共同域名。
注意。 本研究基于在欧洲单一地点采集的 117 个英文实体商品查询及 1536 条回复展开,未测试小语种、虚拟服务类目以及不同地理位置之间的推荐差异。
一句话
AI 生成的商品建议具有高度波动性,并且不同平台的推荐语气与信源分布差异巨大。开发者 API 无法反映真实用户在网页端看到的引用内容,ChatGPT 也更容易使用第一人称直接做出绝对推荐。研究人员和营销团队必须基于真实的网页端进行多轮重复抽样,才能准确评估 AI 对消费者的实际影响。
这篇解读根据论文原文写成,发布前有人看过。引用的段落是原话,数字都是作者自己报告的。方法和完整结果请读论文。